REINFORCEMENT LEARNING & REASONING

Shuo Han 韩硕

I am an AI Algorithm Engineer at Huawei's 2012 Laboratories in Shanghai. I work on reinforcement learning for large language models, with a focus on reasoning, coding, and efficient policy optimization.

My work spans the full RL training loop: data and reward design, large-scale training, and evaluation. I am especially interested in helping models reason more effectively and learn more reliably.

Previously, I interned at NetEase Fuxi AI Lab on game AI. I received my master's degree from Xi'an Jiaotong University and my bachelor's degree from Northeastern University.

LLM Reinforcement Learning / Reasoning & Coding / Policy Optimization

ICML 2026 SpotlightRatio-Variance Regularized Policy Optimization

Experience

From game policies to language model reasoning.
Jul 2024 — PresentShanghai

Huawei · 2012 Laboratories

AI Algorithm Engineer

  • RL training and optimization for language models from 1B to 135B parameters, spanning training diagnostics, tuning, and evaluation.
  • Code reasoning with execution-based feedback, multilingual training data, and reward system development.
  • Efficient chain-of-thought reasoning and policy-ratio variance constraints for more stable off-policy learning.
LLM RLReasoningRLHF / SFT
Apr 2023 — Jul 2023Hangzhou

NetEase · Fuxi AI Lab

Game AI Intern · Reinforcement Learning

  • Mahjong AI development: state and action design, distributed RL training, and containerized environments.
  • Model deployment with Triton, integrating business logic, stateful services, model orchestration, and warm-up.
Multi-Agent RLGame AITriton

Selected Research

Policy learning, efficient reasoning, and multi-agent systems.
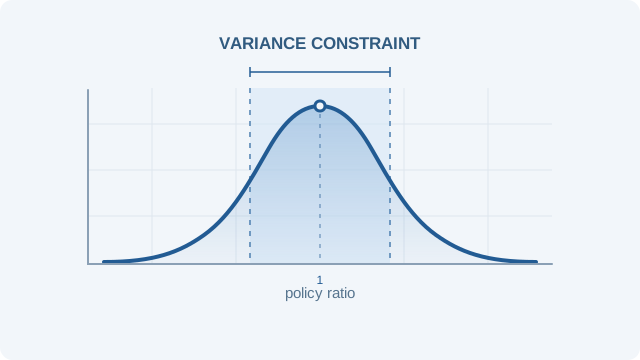
Concept diagram of a policy-ratio distribution within a variance constraint band
ICML 2026Spotlight

Ratio-Variance Regularized Policy Optimization

Yu Luo, Shuo Han, Yihan Hu, Lei Lv, Huaping Liu, Fuchun Sun, Jianye Hao, Dong Li

Regularizing policy-ratio variance to address gradient truncation and improve stability in off-policy reinforcement learning.

Concept diagram of a compact one-billion-parameter language model on an edge chip
Technical ReportCore Contributor

openPangu Embedded-1B: Efficient Small Language Models for Ascend Edge Devices

openPangu Team, Huawei

Core contributor: Shuo Han

Efficient small language models built for Ascend edge devices, connecting language model capabilities with practical deployment.

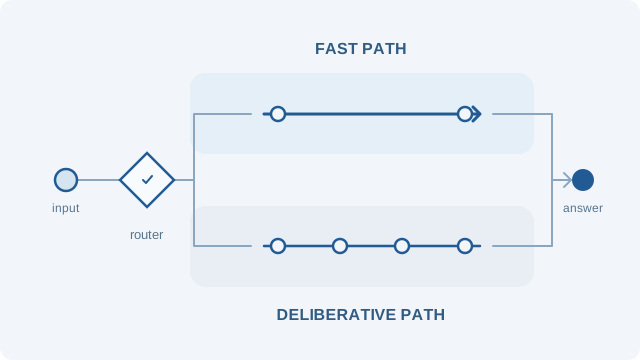
Concept diagram of fast and deliberative reasoning paths selected by a router
arXiv · 2025Contributor

Pangu Embedded: An Efficient Dual-System LLM Reasoner with Metacognition

Pangu Team, Huawei

Contributor: Shuo Han

A dual-system language model reasoner with metacognition, exploring how to balance deliberate reasoning and inference efficiency.

Concept diagram of two teams coordinating and confronting each other in an arena
IEEE ICUS · 2021

Multi-Agent Confrontation Game Based on Multi-Agent Reinforcement Learning

Shuo Han, Liangjun Ke, Zhigang Wang

Studying coordination and confrontation in multi-agent games through reinforcement learning.

Notes & Code

All notes
GITHUBCODE & ENVIRONMENT

Jidi Winter Competition 2022

A 1v1 TableHockey environment with continuous actions for multi-agent reinforcement learning.

Code on GitHub

LET'S CONNECT

Good ideas start with a conversation.

Happy to exchange ideas on reinforcement learning, language models, and reasoning.

hanshuo123i@163.com